Turn papers, interviews, datasets, and notes into a searchable, source-backed research archive.
Your papers, interviews, recordings, datasets, and editorial notes become one research archive: searchable by meaning, structured around sources and entities, reviewable by editors, and traceable back to citations.
I can't offer a full literature review here — but from our own reports and briefs I can summarise what we've found on winter energy poverty, and link each claim to its source.
The risk concentrates in low-income households in poorly-insulated housing, where a cold snap forces a choice between heating and other essentials — and it falls hardest on older people and families with young children.1
Short-term payments ease the immediate crisis, but the durable gains in our data come from fabric measures — insulation and efficient heating — that lower the bill every winter, not just this one.2
Coverage drops off on long-term outcomes; most sources track the season they were written in, so claims about multi-year impact aren't well-supported yet.3
Three things at once — archive, publication site, and reader workspace.
A structured research corpus, a publication site rendered from it, and reader tools for search, citation, saving, and exploration.
Archive
A structured editorial corpus — entities, relationships, and source material, not a pile of files.
- Papers & preprints
- Interviews
- Datasets
- Editorial notes
Publication site
A publication site rendered straight from the corpus.
- Issue & paper pages
- Interview pages
- Dataset pages
- Contributor pages
Reader workspace
Readers who can ask, cite, save, follow, and explore the corpus.
- Ask & search
- Cite & export
- Save & follow
- Explore entities
Publications that stay connected to their source.
Papers, interviews, and datasets stay connected after publication — searchable, reusable, and linked back to their sources.
Connected to source
Publications stay linked to the material they draw on.
Always discoverable
Interviews and datasets remain findable, not buried in supplements.
Citations travel
Every answer arrives with the citation trail attached.
Reviewed translation
Translations enter editorial review before they're published.
Move across entities
Readers cross issues, authors, topics, and source types freely.
A folder stores files. A research archive holds relationships.
The difference isn't storage — it's structure. Entities, citations, and relationships are what make a corpus answerable.
- —Files
- —Weak context
- —Static PDFs
- —Disconnected interviews
- —No relationships
- +Entities
- +Citations
- +Relationships
- +Source-backed answers
- +Reader-facing research surfaces
The pipeline stays visible.
From import to publication, every step is something your editors can see and steer — not a black box.
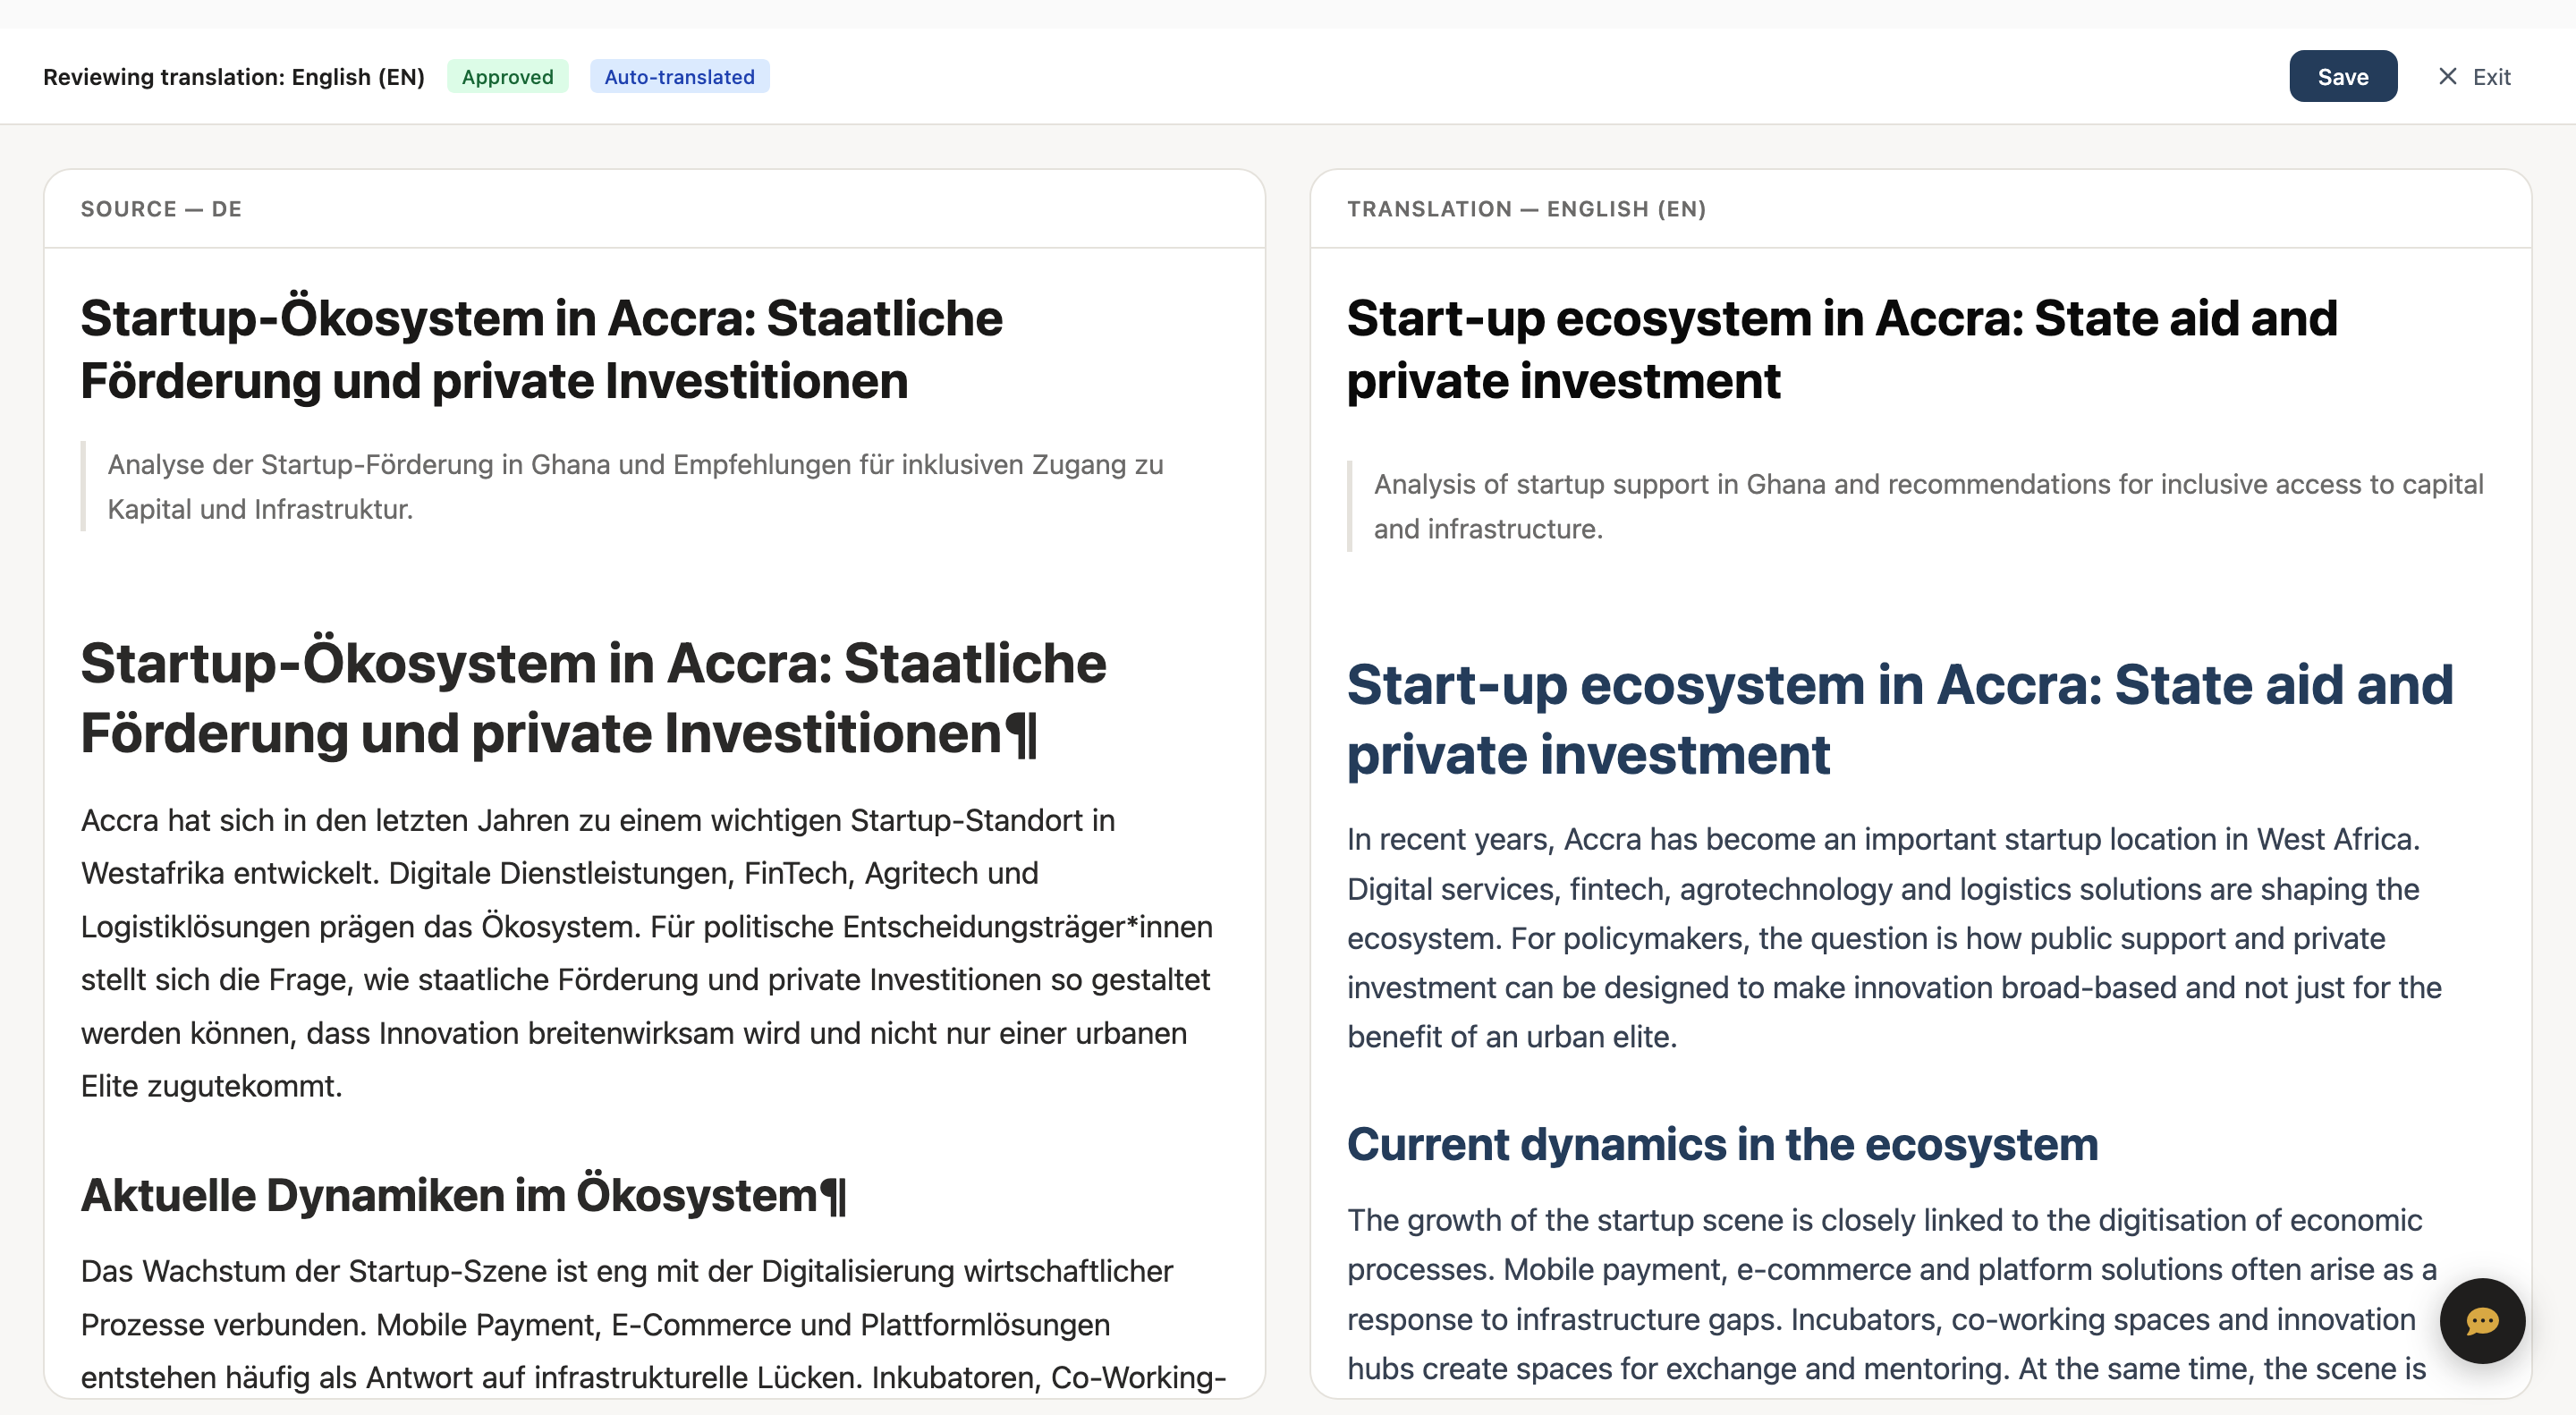
Answers you can actually cite.
Every answer resolves to specific, citable targets — a paper section, an interview timestamp, a dataset reference, a footnote, an editorial note.
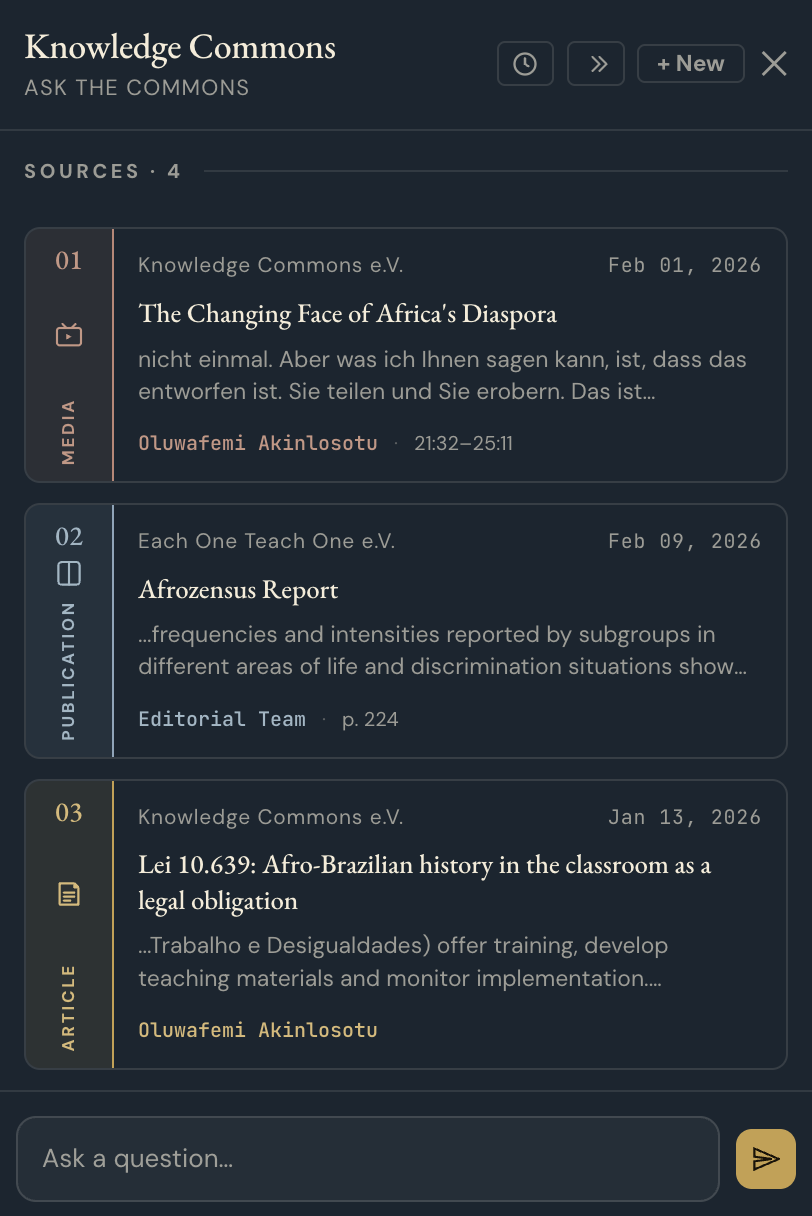
Readers need more than a linear article page.
They follow a citation into an interview, jump to a dataset, save a paper, and continue in a supported language. The archive should move with them.
A corpus is a network of entities.
Issues, series, authors, interviews, datasets, topics, places, funders, publications, and footnotes — linked, not listed.
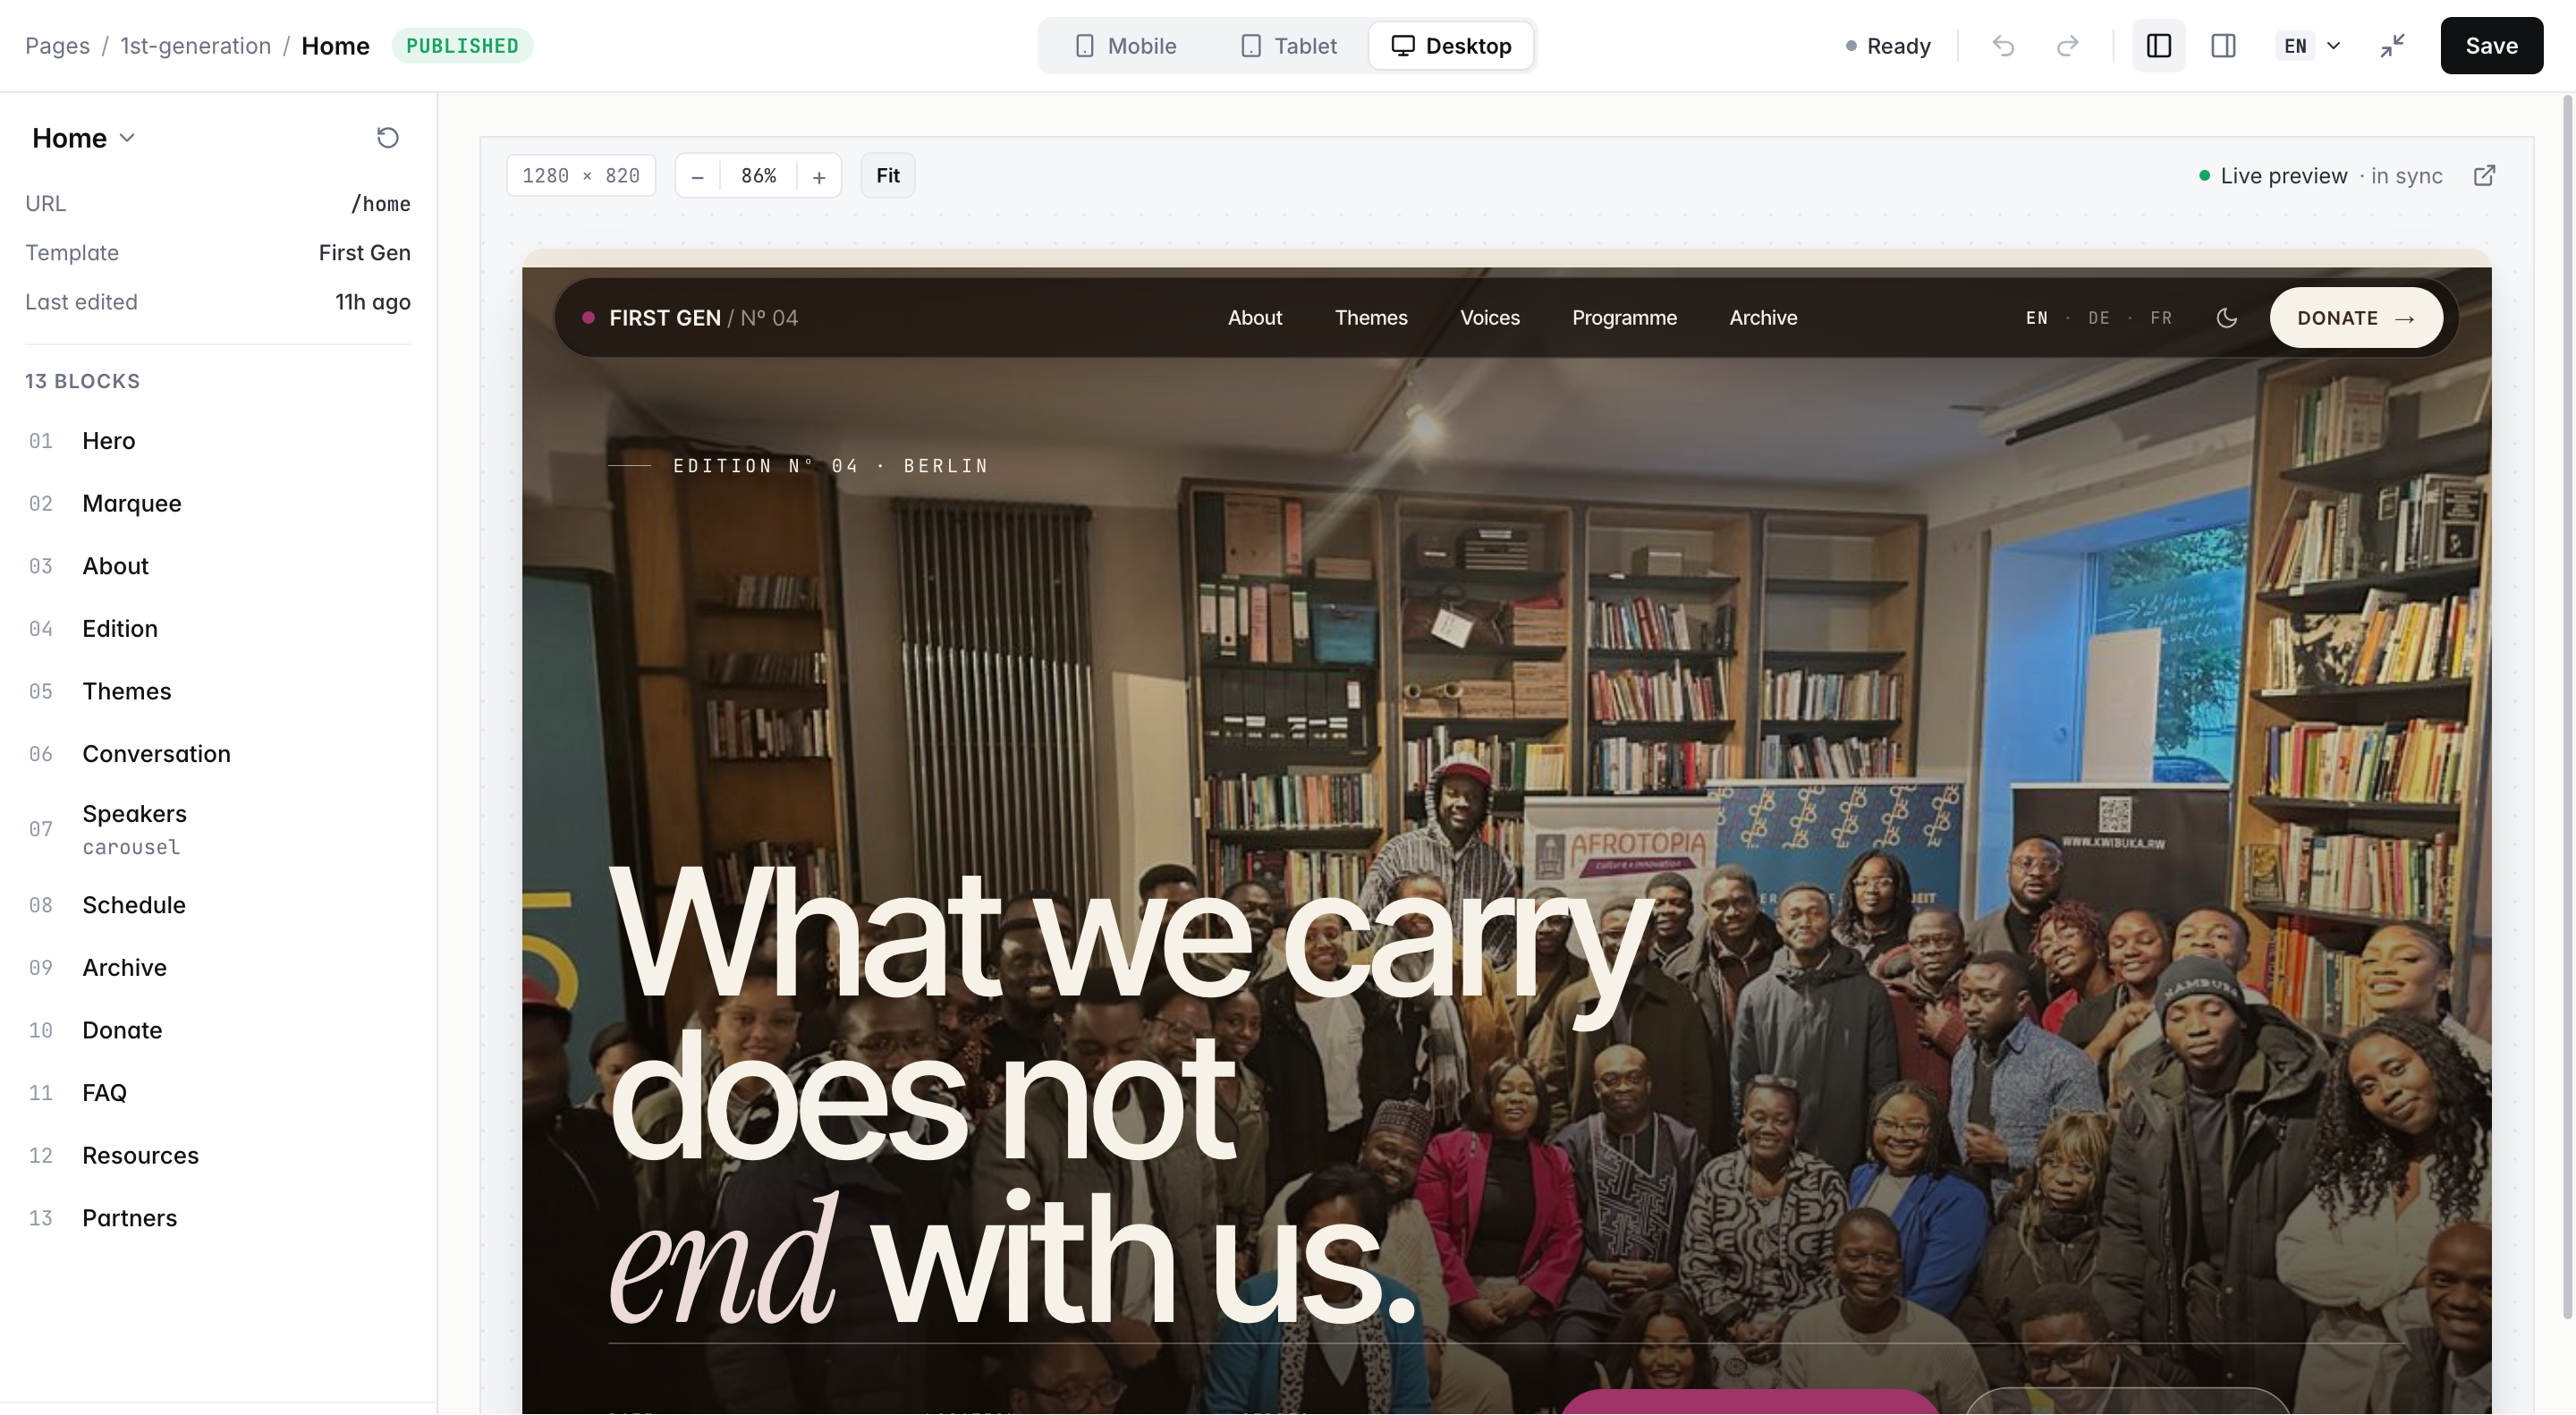
Add retrieval to your publication — or launch an archive-first site.
Keep your existing publication site and add search, ask, and citation surfaces — or launch a complete archive-first site. Same corpus, same permissions, same citation trail.
Embed into your existing publication
Drop-in- Search
- Ask widget
- Citation cards
- Dataset references
- Related material
- Multilingual
Launch an archive-first site
Public site · mobile-ready- Issue pages
- Paper pages
- Interview pages
- Dataset pages
- Contributor pages
- Multilingual editions
Separate editorial archives. Shared research surfaces.
A consortium can pool published work without any team losing control of its own corpus, citations, or revision history.
citation intact
Editorial archives
Each team keeps its own workspace, reviewers, permissions, and corpus.
Shared collections
Approved collections can be shared, with citation and attribution kept intact.
Governed federation
Withdrawal and revision history stay visible across the shared surface.
Five surfaces, one corpus.
From a private editorial draft to a public consortium surface, every item sits exactly where you place it.
Private editorial workspace
Drafts and working material, visible to your team only.
Reviewer-only material
Shared with named reviewers during editorial review.
Member-access archive
Open to members or subscribers of your publication.
Public site
Published openly under your own identity.
Shared consortium surface
Approved collections, discoverable across the consortium.
Built for work that will be cited.
Provenance, review, and correction are part of the record — not an afterthought bolted on at publication.
Citation provenance
Every claim resolves to the exact source it was drawn from.
Editorial review
Abstracts, citations, and outputs pass through editorial review.
Translation review
Translations are reviewed and approved before publication.
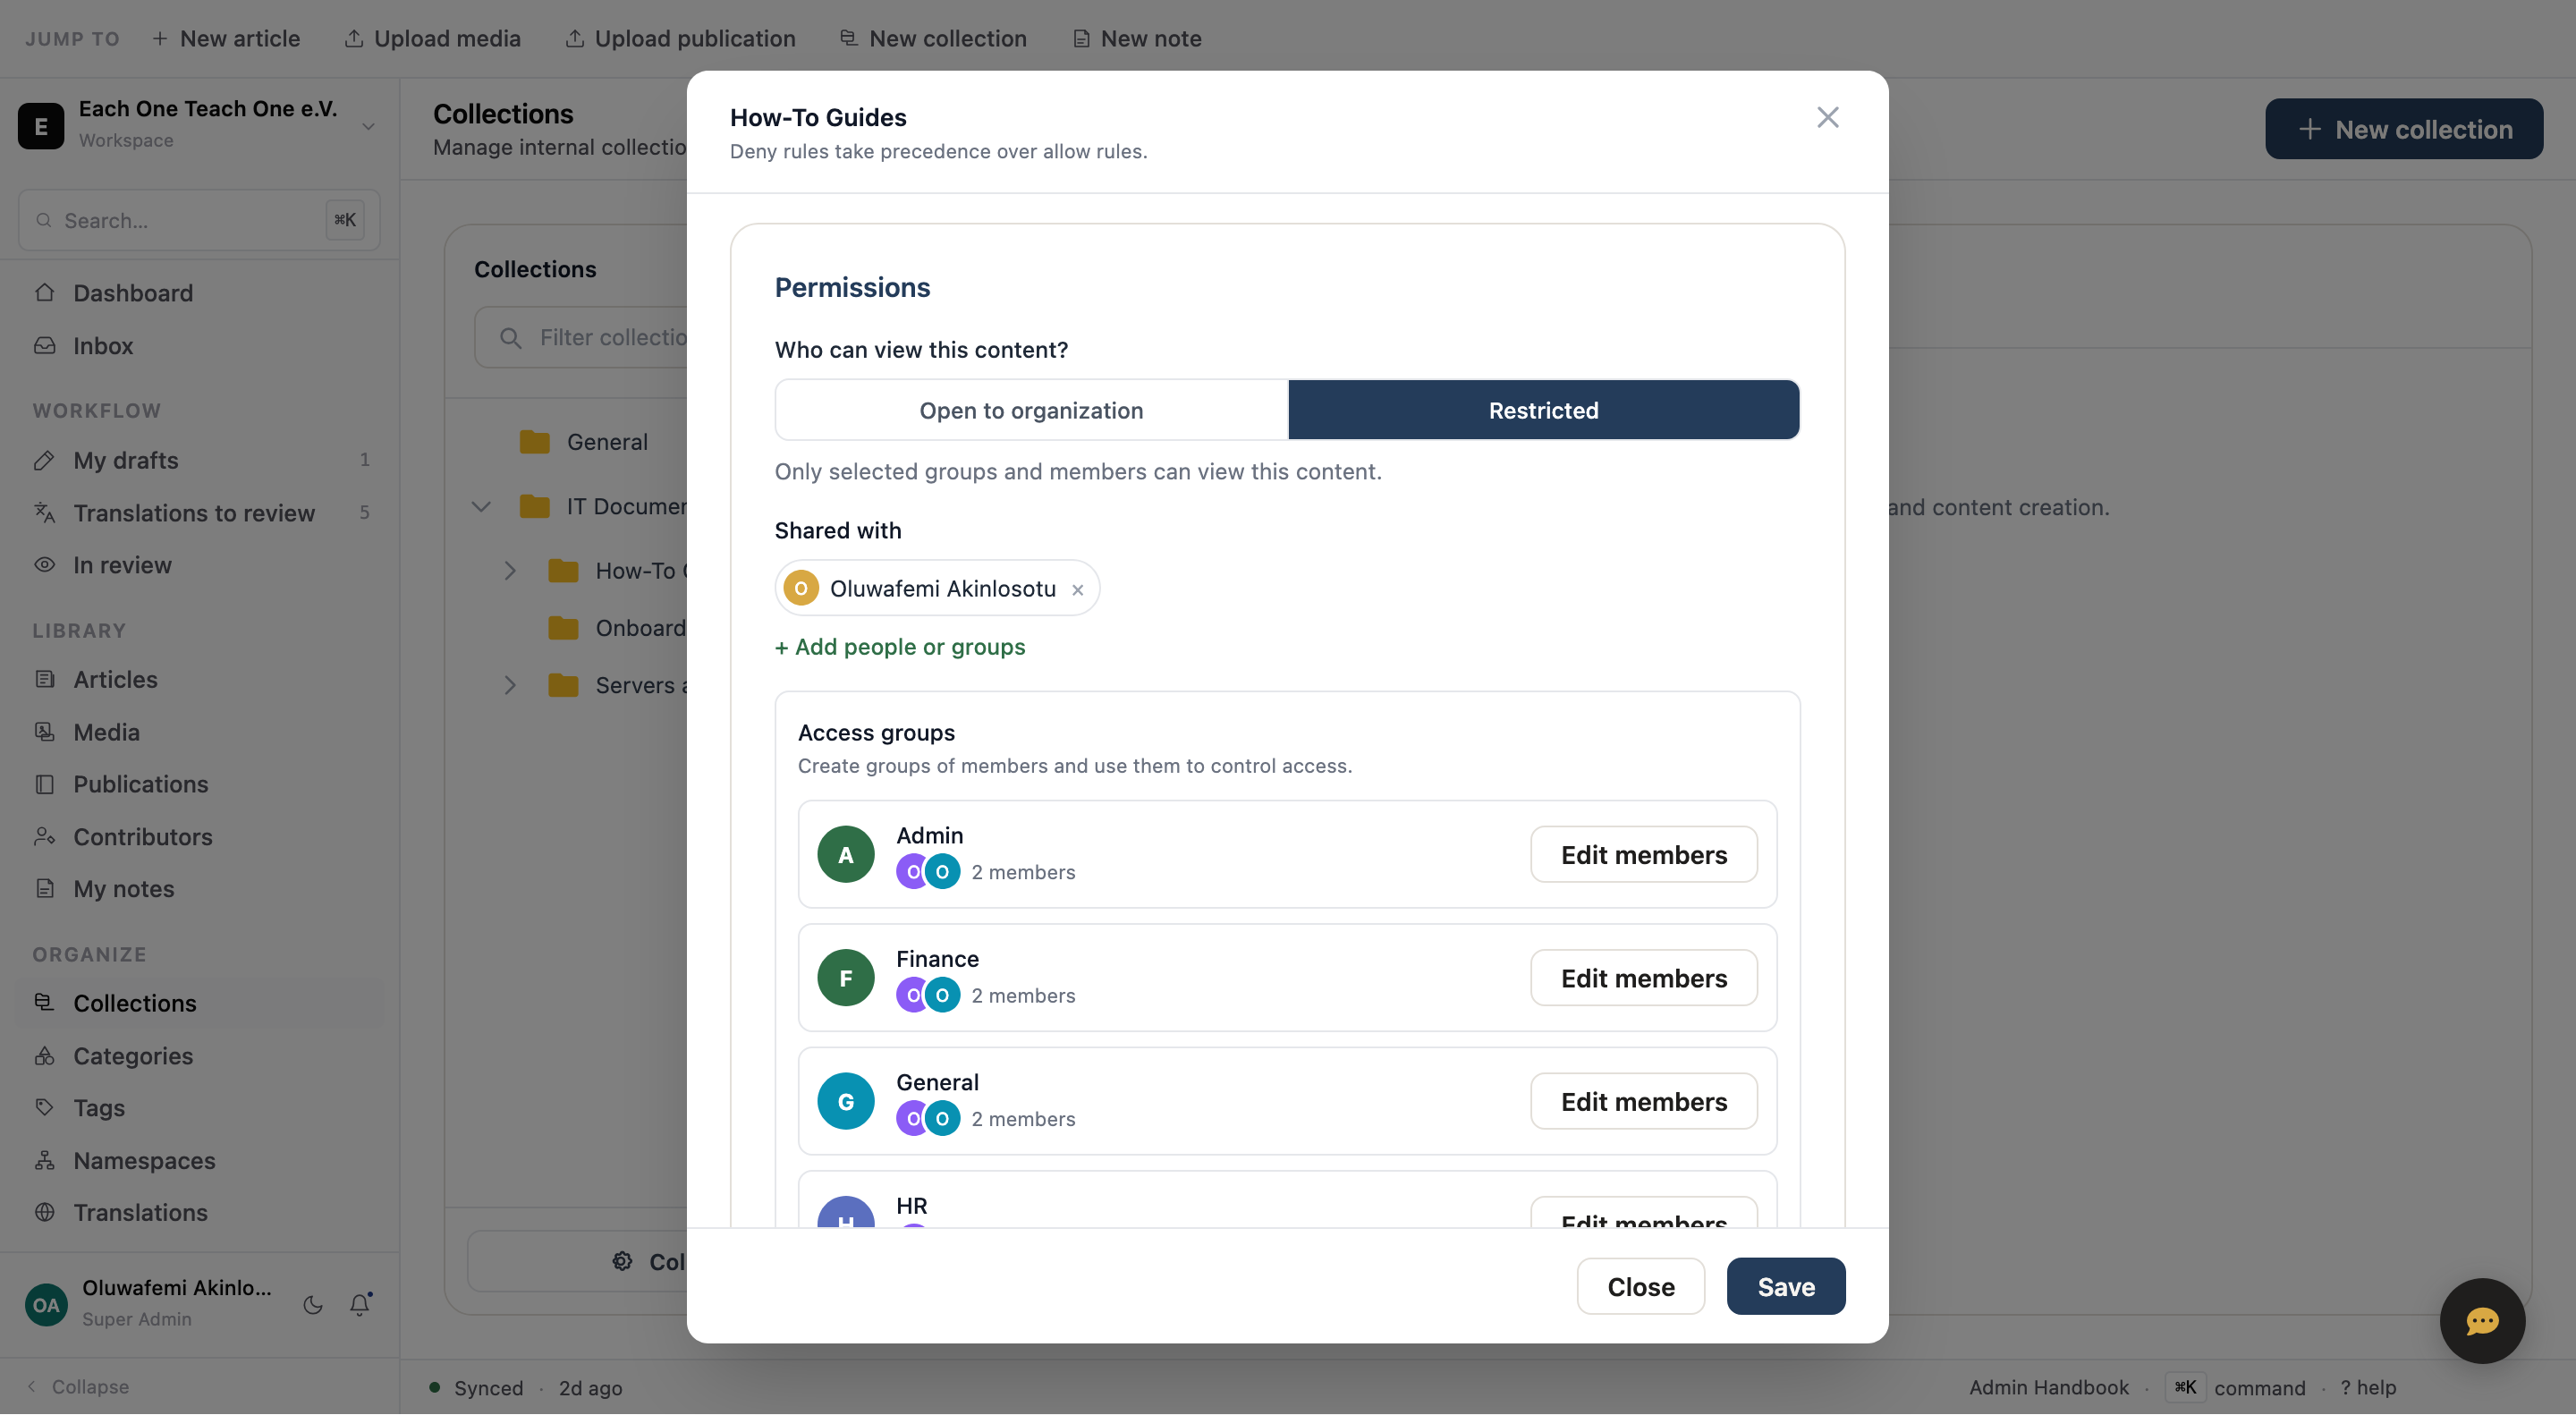
Permissions
Restrict by workspace, reviewer, member, collection, or source.
Audit trail
EU-hosted by default, with traceable activity across the corpus.
Source correction path
Corrections and revisions are recorded, with history kept visible.
Start with papers, interviews, and datasets.
Your pilot starts with the corpus you already have. Your team can test a searchable research archive where readers verify, cite, ask, and explore.
- ✓Start from papers, interviews, datasets, recordings & notes
- ✓Build a source-backed publication site
- ✓Readers can verify, cite, and explore
- ✓Editorial & translation review built in
- ✓EU hosting with a full audit trail
Frequently Asked Questions
Straight answers on citations, structure, multilingual review, datasets, and what readers can actually do.
Can every answer cite the exact source? +
Yes. Answers resolve to source-backed targets: paper sections, interview timestamps, dataset references, footnotes, editorial notes, or other source material. Readers can follow the answer back to where it came from.
Can readers trace a summary back to the underlying material? +
Yes. Summaries link back to the paper, interview, dataset, timestamp, footnote, or editorial note they draw from, so readers can verify claims instead of treating summaries as detached AI output.
Can generated summaries and translations enter editorial review before publication? +
Yes. Summaries, abstracts, translations, and other AI-assisted outputs move through editorial review before publication. Your team stays in control of how material is represented across supported languages.
Can Loracta handle conflicting sources or multiple interpretations? +
Yes. When material contains disagreement, revision, or competing interpretations, answers surface the relevant sources instead of flattening them into a single unsupported conclusion. Editorial judgment stays visible.
What happens when a source is corrected or revised? +
Corrections and revisions remain visible in the archive workflow. Updated material is reindexed, public pages are refreshed, and source trails continue pointing readers to the current approved version.
Can some material stay private for researchers or editors only? +
Yes. Private working material, reviewer-only sources, embargoed content, internal notes, member-access material, and public resources stay separated, so teams can publish from the archive without exposing the whole archive.
Can Loracta distinguish between draft, reviewed, published, corrected, and archived material? +
Yes. Material moves through workflow states such as draft, internal, reviewed, published, corrected, or archived, keeping public answers, citations, and summaries aligned with the current approved version.
Can Loracta preserve contributor, funder, rights, and license metadata? +
Yes. Contributors, funders, rights notes, publication dates, source types, licenses, places, datasets, and editorial context remain attached to archive records, preserving the intellectual and institutional context around each source.
Can Loracta preserve our existing editorial structure? +
Yes. Issues, series, contributors, topics, interviews, datasets, publications, places, funders, and source types remain meaningful entities in the archive. Your structure becomes more searchable and usable, not flattened into a file dump.
Can we launch an archive-first site without rebuilding our whole publication workflow? +
Yes. Your existing publication workflow can stay in place while search and citation surfaces are embedded into the current site, or your team can launch dedicated archive-first pages for issues, papers, interviews, datasets, contributors, and collections.
Can readers export citations? +
Yes. Citation export is supported where source metadata is available, especially for papers, interviews, datasets, and longform editorial work that readers need to reference outside the site.
Can interviews and recordings be cited by timestamp? +
Yes. Audio and video material can be transcribed and linked back to timestamps, allowing readers to move from an answer, quotation, or summary to the exact moment in the source.
Can readers ask questions across multiple languages? +
Yes. Readers can search and ask across the languages your archive supports, discovering relevant material originally written, recorded, or translated in another language.
Can several research groups contribute to one shared archive or knowledge hub? +
Yes. Separate research groups keep their own archives while contributing approved collections into a shared research surface, consortium archive, oral-history project, or thematic knowledge hub. Attribution, citations, permissions, and review status remain attached to each source.
Make your research answerable.
Start with the research material you already hold — papers, interviews, datasets, recordings, and editorial notes. In the pilot, your team can test a searchable, source-backed research archive where readers verify, cite, ask, and explore.